Benchmarks
We benchmark quality and speed across all methods on ~1,250 queries over 63 repositories in 19 languages.
Main Results
| Method | NDCG@10 | Index time | Query p50 |
|---|---|---|---|
| semble | 0.854 | 306 ms | 0.91 ms |
| CodeRankEmbed | 0.839 | 116 s | 16 ms |
| ColGREP | 0.693 | 5.4 s | 122 ms |
| BM25 | 0.673 | 47 ms | 0.17 ms |
| zvec-grep | 0.670 | 3.4 s | 391 ms |
| ck | 0.642 | 96 s | 187 ms |
| codebase-memory-mcp | 0.630 | 454 ms | 46 ms |
| grepai | 0.561 | 35 s | 48 ms |
| probe | 0.387 | - | 207 ms |
| cs | 0.200 | - | 22 ms |
| ripgrep | 0.126 | - | 14 ms |
Semble matches the NDCG@10 of the 137M-parameter CodeRankEmbed while indexing ~380× faster and answering queries ~17× faster, entirely on CPU.
NDCG@10 is averaged across all queries. Speed numbers use one repo per language, CPU only: cold-start index time and warm query p50 (median across 5 consecutive runs). The charts below plot latency against NDCG@10. Marker size reflects model parameter count.
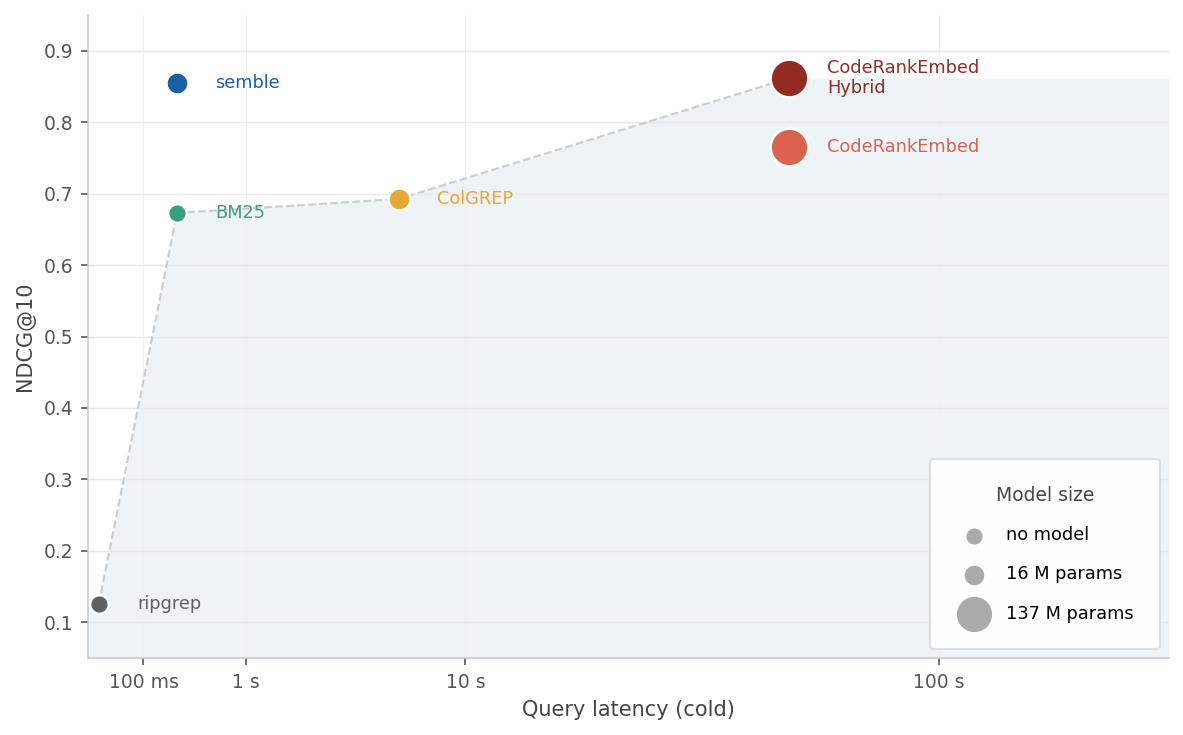 Time to first result (index + query) vs NDCG@10
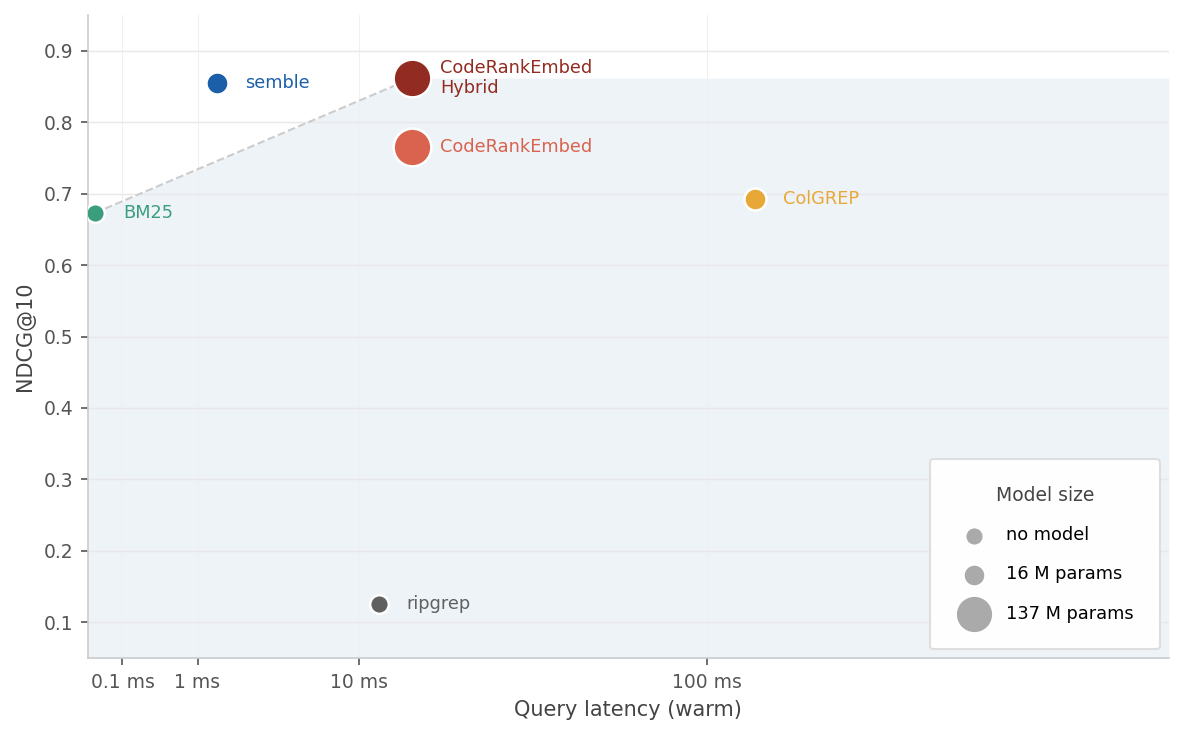 Query latency on a warm index vs NDCG@10
Token Efficiency
Coding agents (Claude Code, OpenCode, etc.) typically find code by running grep on keywords and reading the matched files. We model that workflow and compare it against semble’s chunk retrieval across our full benchmark of 1,251 queries.
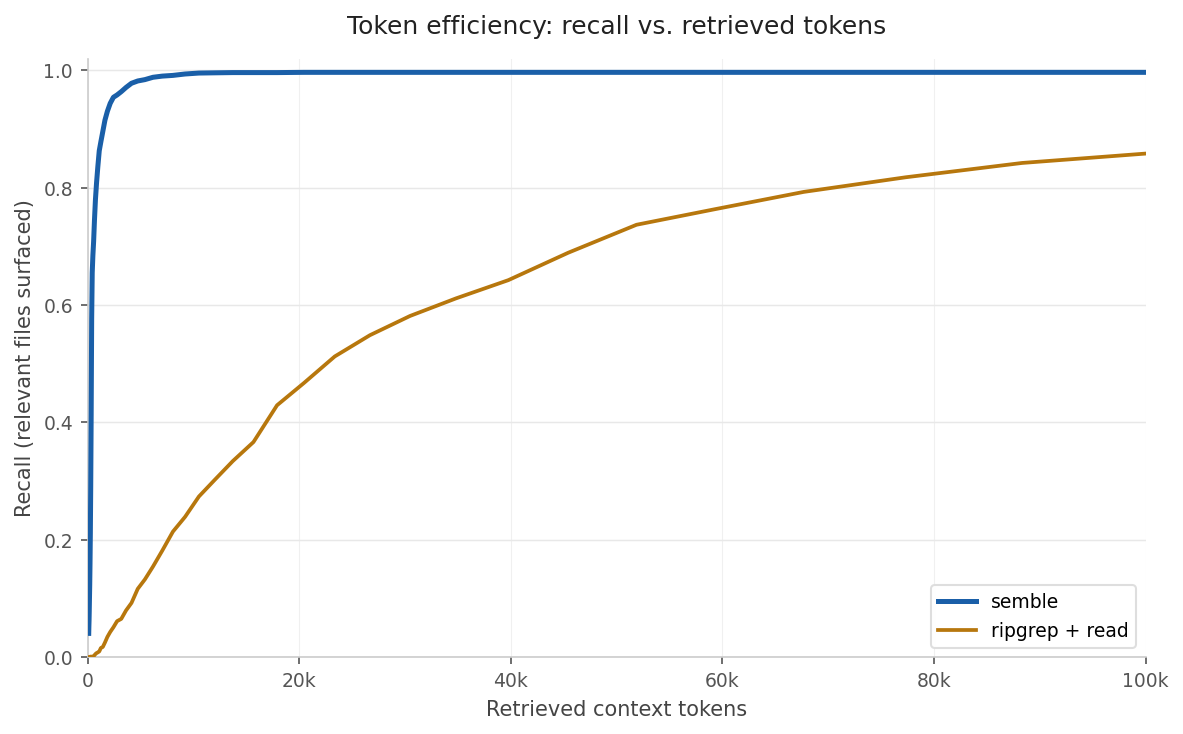
Expected tokens per query
For each query: tokens consumed at first relevant hit, or 32k if the method never finds anything. Averaged across all 1,251 queries.
| Method | Expected tokens | Savings |
|---|---|---|
| ripgrep + read file | 45,587 | baseline |
| semble | 348 | 99% fewer |
Recall at fixed token budgets
A relevant file is “covered” once any retrieved unit comes from it.
| Method | 500 | 1k | 2k | 4k | 8k | 16k | 32k |
|---|---|---|---|---|---|---|---|
| semble | 0.842 | 0.923 | 0.967 | 0.988 | 0.995 | 0.995 | 0.995 |
| ripgrep + read file | 0.001 | 0.008 | 0.037 | 0.086 | 0.207 | 0.374 | 0.583 |
Methodology
Semble returns the top-50 ranked chunks. ripgrep+read splits the query into keywords (dropping stopwords and short words), runs rg --fixed-strings --ignore-case for each keyword, then reads matched files in full ranked by how many distinct keywords they contain. Both methods search the same set of file types and ignored directories. Tokens are counted with cl100k_base via tiktoken. A relevant file is “covered” once any retrieved unit overlaps its annotated span.
By Language
NDCG@10 per language, sorted by semble. CRE = CodeRankEmbed, cbm = codebase-memory-mcp. Best score per row is bolded.
| Language | semble | CRE | ColGREP | zvec-grep | ck | cbm | grepai | probe | cs | ripgrep |
|---|---|---|---|---|---|---|---|---|---|---|
| javascript | 0.917 | 0.925 | 0.823 | 0.760 | 0.772 | 0.770 | 0.675 | 0.588 | 0.171 | 0.176 |
| cpp | 0.915 | 0.897 | 0.626 | 0.677 | 0.687 | 0.630 | 0.731 | 0.375 | 0.262 | 0.126 |
| zig | 0.913 | 0.911 | 0.474 | 0.664 | 0.511 | 0.766 | 0.755 | 0.369 | 0.121 | 0.000 |
| scala | 0.909 | 0.925 | 0.765 | 0.799 | 0.717 | 0.704 | 0.330 | 0.392 | 0.111 | 0.180 |
| ruby | 0.909 | 0.905 | 0.708 | 0.758 | 0.738 | 0.689 | 0.643 | 0.382 | 0.255 | 0.230 |
| go | 0.895 | 0.713 | 0.785 | 0.512 | 0.458 | 0.506 | 0.722 | 0.410 | 0.183 | 0.133 |
| elixir | 0.894 | 0.893 | 0.808 | 0.811 | 0.786 | 0.506 | 0.669 | 0.412 | 0.397 | 0.134 |
| csharp | 0.885 | 0.848 | 0.614 | 0.609 | 0.548 | 0.775 | 0.277 | 0.392 | 0.248 | 0.117 |
| python | 0.867 | 0.878 | 0.777 | 0.704 | 0.721 | 0.643 | 0.634 | 0.488 | 0.305 | 0.202 |
| swift | 0.860 | 0.845 | 0.710 | 0.709 | 0.672 | 0.630 | 0.429 | 0.280 | 0.151 | 0.160 |
| php | 0.858 | 0.847 | 0.663 | 0.583 | 0.615 | 0.608 | 0.402 | 0.340 | 0.180 | 0.123 |
| rust | 0.856 | 0.754 | 0.662 | 0.541 | 0.419 | 0.454 | 0.519 | 0.242 | 0.193 | 0.162 |
| java | 0.849 | 0.790 | 0.641 | 0.685 | 0.606 | 0.554 | 0.386 | 0.536 | 0.136 | 0.198 |
| bash | 0.825 | 0.834 | 0.706 | 0.725 | 0.677 | 0.768 | 0.723 | 0.226 | 0.170 | 0.000 |
| lua | 0.823 | 0.829 | 0.798 | 0.736 | 0.738 | 0.591 | 0.699 | 0.336 | 0.050 | 0.000 |
| kotlin | 0.821 | 0.823 | 0.637 | 0.628 | 0.587 | 0.611 | 0.478 | 0.335 | 0.170 | 0.166 |
| haskell | 0.765 | 0.811 | 0.683 | 0.689 | 0.733 | 0.624 | 0.483 | 0.313 | 0.160 | 0.000 |
| c | 0.741 | 0.771 | 0.676 | 0.598 | 0.606 | 0.655 | 0.555 | 0.384 | 0.175 | 0.000 |
| typescript | 0.706 | 0.671 | 0.430 | 0.476 | 0.456 | 0.455 | 0.394 | 0.354 | 0.145 | 0.128 |
| overall | 0.854 | 0.839 | 0.693 | 0.670 | 0.642 | 0.630 | 0.561 | 0.387 | 0.200 | 0.126 |
Ablations
raw returns retrieval scores directly; + ranking feeds them through semble’s hybrid ranker.
| Retrieval | Raw | + ranking |
|---|---|---|
| BM25 | 0.675 | 0.834 |
| potion-code-16M-v2 | 0.650 | 0.821 |
| BM25 + potion-code-16M-v2 | - | 0.854 |
By query category:
| Mode | Architecture | Semantic | Symbol |
|---|---|---|---|
| BM25 raw | 0.628 | 0.676 | 0.719 |
| potion-code-16M raw | 0.626 | 0.666 | 0.629 |
| semble BM25 (+ ranking) | 0.770 | 0.819 | 0.957 |
| semble potion-code-16M (+ ranking) | 0.757 | 0.808 | 0.943 |
| semble hybrid | 0.802 | 0.846 | 0.958 |
Dataset
~1,250 queries over 63 repositories in 19 languages, grouped into three categories:
| Category | Queries | What it tests |
|---|---|---|
| semantic | 711 | Code that implements a specific behavior or concept |
| architecture | 343 | Design decisions, module boundaries, structural patterns |
| symbol | 204 | Named entity lookup (function, class, type, variable) |
Three repos per language (nine for Python): bash, C, C++, C#, Elixir, Go, Haskell, Java, JavaScript, Kotlin, Lua, PHP, Python, Ruby, Rust, Scala, Swift, TypeScript, Zig. Repos are pinned by revision. Queries and ground-truth relevance labels are generated by Claude Sonnet 4.6, and the same model is used as LLM-as-judge to verify label quality.
Methods
- ripgrep: fast regex search, included as a raw keyword-match baseline.
- probe: BM25 keyword ranking backed by tree-sitter parse trees. No persistent index; scans on the fly.
- cs (Code Spelunker): structural BM25 ranker that ranks matches differently in code, comments, and strings.
- ColGREP: late-interaction code retrieval with the LateOn-Code-edge model.
- grepai: semantic search using nomic-embed-text (137M params) via a local Ollama daemon.
- codebase-memory-mcp: code intelligence engine that indexes a repo into a SQLite/graph store. Benchmarked via its
search_graphtool infastmode (BM25 full-text search with structural boosting). - ck: hybrid regex + semantic search using bge-small-en-v1.5.
- zvec-grep: potion-code-16M-v2 static embeddings + BM25, benchmarked in
directmode. - CodeRankEmbed: 137M-param transformer embedding model for code retrieval, used for semantic-only dense search.
- semble: potion-code-16M-v2 static embeddings + BM25 + the semble reranking stack.
Several other tools (codanna, claude-context, GitNexus, codegraph, tgrep) were considered but excluded, either because they don’t support a large share of the benchmark languages, require paid API keys, or produce results nearly identical to ripgrep. See the benchmarks README for details and instructions for reproducing the results.